The governance programme I meet most often starts with a 60-page policy pack, a steering committee and a six-month tooling RFP. Six months later the lakehouse is still growing, nobody owns half the gold tables, and the policy PDF sits unread. I’ve seen that pattern on both Databricks and Microsoft Fabric programmes. The fix isn’t more policy. It’s a data governance framework for a lakehouse that fits on one page: five roles, six controls, and a place to put each control in the platform you already run.
This is the minimum viable model I start with. It borrows lightly from familiar DMBOK ideas (ownership, stewardship, classification, quality) without trying to implement a full body of knowledge. It works whether your catalog is Unity Catalog or Fabric with Purview behind it. And it grows with the platform instead of blocking it.
Product behaviour described here reflects Databricks and Microsoft Fabric / Purview documentation (docs.databricks.com and Microsoft Learn) as of November 2026. Both platforms move quickly, so check the linked docs before relying on any detail.
Why big-bang governance programmes stall
Big-bang programmes stall for predictable reasons:
- They invent a parallel organisation. A central governance office that doesn’t own any pipelines can’t enforce anything. Reviews become theatre.
- They pick tooling before roles. A catalog without a named owner per domain is just searchable chaos.
- They try to classify everything on day one. Full-estate classification is a multi-year programme. Useful governance starts with the tables people actually query.
- They ignore cost. Compute and storage without an owner become everyone else’s problem, and the bill is what finally forces a conversation.
A minimum model flips the order: name the roles, pick the few controls that change behaviour, implement them in the catalog you already have, and make the gaps visible. Policy documents come later, as a record of what already works.
The five roles you actually need
I keep five roles. Titles vary by organisation; the responsibilities shouldn’t.
- Data owner. Accountable for a domain or a set of tables. Approves who can use the data, what “good” means, and what happens when quality fails. Usually a business lead, not an engineer.
- Data steward. The day-to-day curator: classifications, descriptions, quality rules, access requests. Often a senior analyst or analytics engineer embedded in the domain.
- Platform engineer. Runs the lakehouse: catalogs, workspaces, capacities, CI/CD, monitoring. Owns the rails, not the data content. Workspace layout matters here; see my Fabric workspace structure guide.
- Data consumer. Analysts, report authors, data scientists and (increasingly) AI agents. They need discoverable, certified data and a clear path to request access.
- Security / compliance. Sets the classification scheme, sensitivity labels, audit and retention expectations. Reviews exceptions; does not own every table.
Those five map cleanly onto a RACI. Owners are Accountable, stewards are Responsible for most day-to-day controls, platform is Responsible for the machinery, consumers are Consulted or Informed, and security is Consulted on classification and access patterns that touch regulated data.
The minimum controls in a data governance framework for a lakehouse
Six controls cover almost every governance conversation I have on a lakehouse. If a control doesn’t change who can act, what they can see, or what they can measure, I leave it out of the minimum set.
| Control | What “done” looks like |
|---|---|
| Ownership | Every catalog/schema (or Fabric domain/workspace) has a named owner and steward in metadata, not in a spreadsheet. |
| Classification | Sensitivity and domain tags on tables (and columns where it matters); unlabeled production gold is a visible exception. |
| Access | Grants go to groups, not individuals; least privilege by default; elevated access is time-boxed and audited. |
| Quality | Rules run in the pipeline with a defined outcome (quarantine / fail) and a named owner on the alert. |
| Lineage | Upstream sources and downstream reports are visible before you change a gold table. |
| Cost | Every workspace/catalog maps to a cost centre or capacity owner; spend is reviewed on a fixed cadence. |
That’s the skeleton teams can adopt without waiting for a multi-year programme. Everything else (retention schedules, contract templates, AI-agent policies) layers on once these six are real.
Implementing each control in Unity Catalog and in Fabric/Purview
Same controls, different knobs. I implement both sides the same way: metadata first, then enforcement, then visibility.
Ownership
- Unity Catalog. Put owner and steward on catalogs and schemas with governed tags (or system tags where they fit). Catalog Explorer and
INFORMATION_SCHEMAmake the gaps queryable. During a Hive metastore to Unity Catalog migration, refusing to migrate tables with no named owner is the cheapest cleanup you’ll get. - Fabric / Purview. Assign workspaces to domains, name domain owners, and keep workspace Admin membership aligned with that ownership. Tags on workspaces and items carry cost-centre and steward metadata into the OneLake catalog.
Classification
- Unity Catalog. Governed tags for sensitivity and domain; data classification can propose sensitive tags at scale, which you then review. Column tags drive masks.
- Fabric / Purview. Sensitivity labels from Purview Information Protection on items; Fabric tags for your own taxonomy (domain, retention tier, cost centre). Protection policies and DLP sit on top of labels when the estate needs them.
Access
- Unity Catalog. Privileges on catalogs, schemas and tables to account-level groups; row filters and column masks, increasingly via ABAC policies on governed tags rather than one-off grants. Prefer shared, serverless or dedicated access modes that honour UC.
- Fabric. Workspace roles (Admin, Member, Contributor, Viewer) for coarse control; OneLake / item permissions and, where needed, RLS in semantic models. Keep production Writers small; most consumers should be Viewers of certified content.
Quality
This control is pipeline work, not catalog work. Use the bronze-to-gold pattern from my data quality playbook: schema and volume checks early, uniqueness and referential checks before gold publish, quarantine or fail with an owner on the alert. On Databricks, Lakeflow Declarative Pipeline expectations or a shared PySpark library; on Fabric, the same rules in notebooks or Data Factory activities writing to a results table.
Lineage
- Unity Catalog. Built-in table and column lineage across notebooks, jobs and dashboards. Query lineage system tables when you need estate-wide impact analysis.
- Fabric. Workspace lineage and impact analysis; Purview when you need cross-platform lineage beyond Fabric.
Cost
- Unity Catalog / Databricks. Tag catalogs and jobs with cost centres; review
system.billing(and related system tables) with the platform team on a fixed cadence. - Fabric. Map workspaces to capacities deliberately, use the Capacity Metrics app, and treat capacity owners as part of the governance RACI — not as an afterthought when throttling starts.
Making governance visible with a simple dashboard
Controls nobody can see don’t survive contact with delivery pressure. I put a thin governance dashboard over the catalog and a few operational tables. The metrics I care about weekly:
- Ownership coverage. % of production schemas / domains with both owner and steward populated.
- Classification coverage. % of gold tables with a sensitivity tag or label; list of unlabeled exceptions.
- Access hygiene. Grants to individuals (should trend to zero); stale groups; open access requests older than the SLA.
- Quality. Open rule failures by owner; time-to-fix; tables publishing to gold with failing uniqueness checks.
- Lineage gaps. Certified semantic models or reports with missing upstream lineage.
- Cost. Top workspaces / jobs by spend; orphaned sandboxes.
On Databricks this is mostly system tables plus your tag inventory. On Fabric it’s OneLake catalog metadata, the scanner APIs, Capacity Metrics and your quality results table. Keep the dashboard boring and shared with owners — a private platform-only view never changes behaviour.
Growing the model as the platform scales
The minimum model is a starting line, not a ceiling. I grow it in this order:
- More domains, same controls. Split catalogs or Fabric domains before inventing new control types.
- Contracts between producers and consumers. Schema, freshness and quality SLAs as a lightweight template once ownership is real.
- Automated classification and ABAC / protection policies. Once tags are trusted, let policies enforce them.
- AI-agent access. Treat agents as another consumer class with least privilege, audited tool calls and certified sources only.
- Cross-platform Purview / UC federation. When the estate spans both, unify classification and lineage rather than rewriting the RACI.
What I don’t do early: a separate governance operating model for every tool, or a request process that takes weeks for a read-only gold table. Friction belongs on write paths and sensitive data, not on discovery of certified content.
One-page governance template
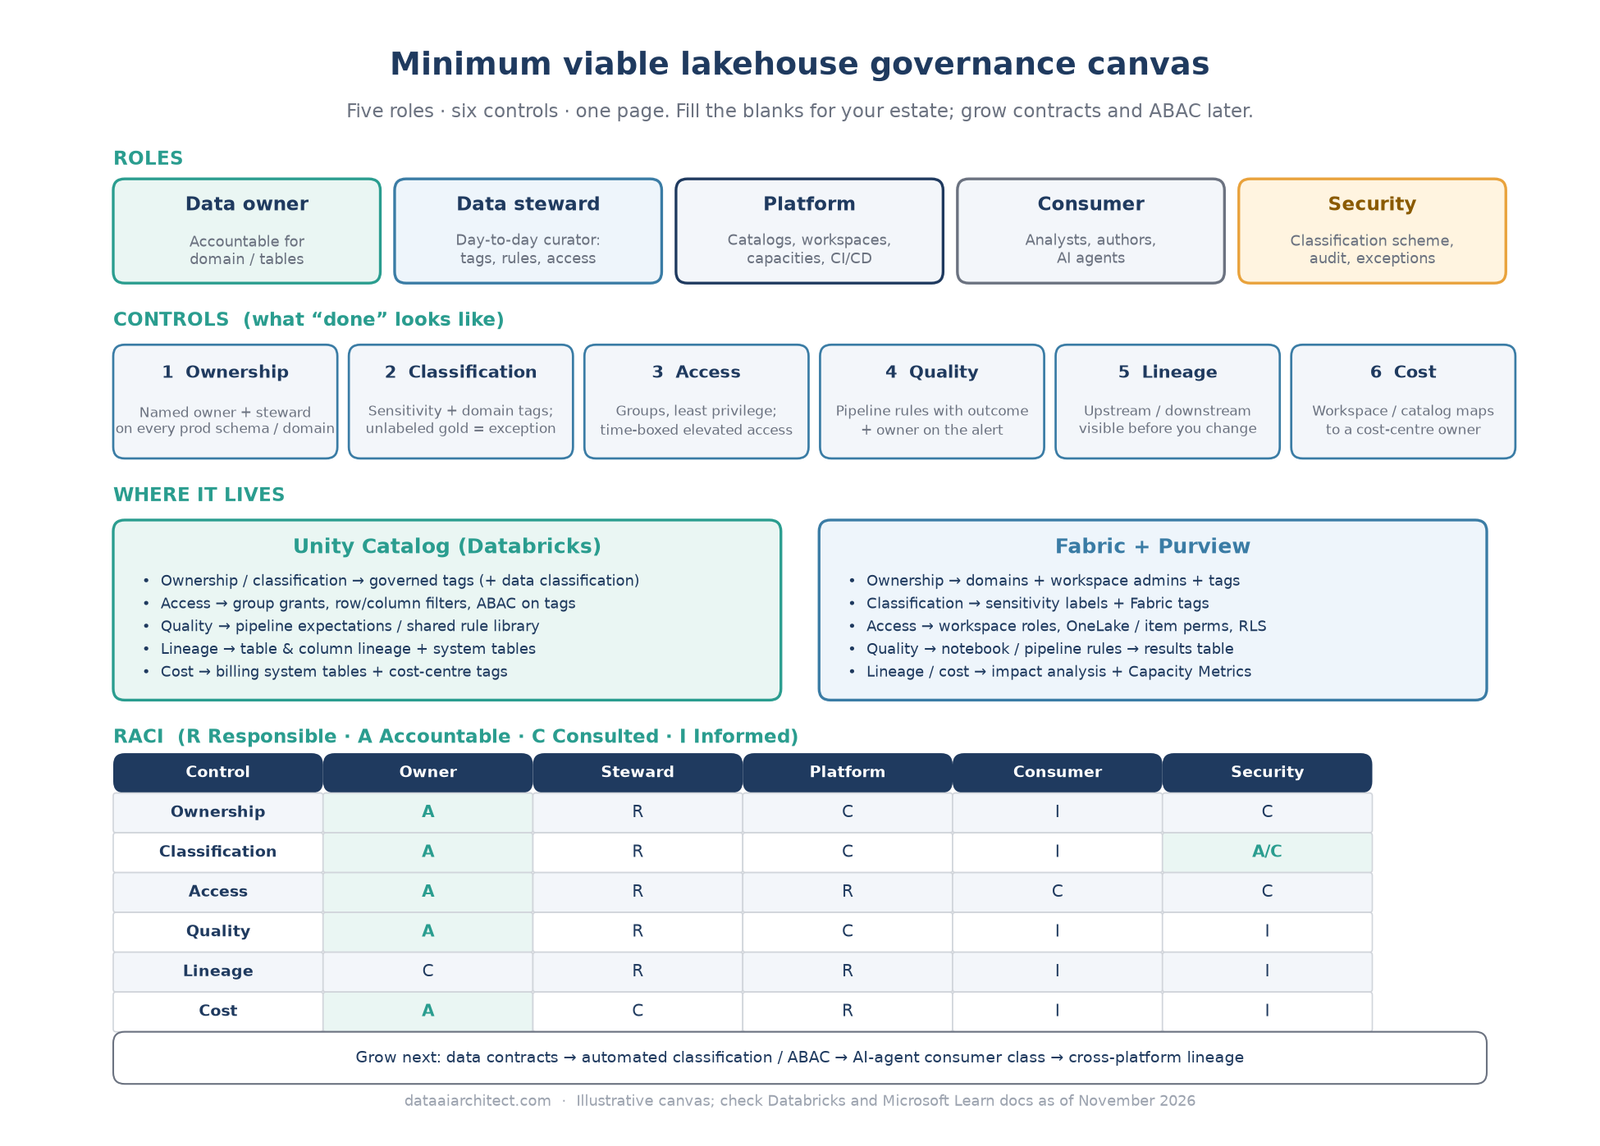
Print this (or paste it into the team’s wiki) and fill the blanks for your estate:
| Role | Named people / group | Notes |
|---|---|---|
| Data owner (per domain) | Accountable for access and quality outcomes | |
| Data steward (per domain) | Responsible for tags, rules, access triage | |
| Platform | Catalogs, workspaces, capacities, CI/CD | |
| Security / compliance | Classification scheme, audit, exceptions | |
| Consumers | How they discover and request access |
| Control | Where it lives (UC / Fabric) | Evidence this week |
|---|---|---|
| Ownership | Tags / domains | Coverage % |
| Classification | Tags / sensitivity labels | Unlabeled gold list |
| Access | Groups + ABAC / workspace roles | Individual grants = 0 goal |
| Quality | Pipeline rules + results table | Open failures by owner |
| Lineage | UC lineage / Fabric impact analysis | Gaps on certified models |
| Cost | Billing tags / Capacity Metrics | Owner review date |
RACI for the six controls
| Control | Owner | Steward | Platform | Consumer | Security |
|---|---|---|---|---|---|
| Ownership | A | R | C | I | C |
| Classification | A | R | C | I | A/C |
| Access | A | R | R | C | C |
| Quality | A | R | C | I | I |
| Lineage | C | R | R | I | I |
| Cost | A | C | R | I | I |
R = Responsible, A = Accountable, C = Consulted, I = Informed. Security shares Accountability with the owner on classification where regulation demands it; otherwise Consulted.
Key takeaways
- Big-bang governance stalls; a one-page model with five roles and six controls ships.
- Ownership and classification in metadata beat policy PDFs that nothing enforces.
- Implement the same controls in Unity Catalog and in Fabric/Purview; don’t invent a second operating model.
- Make gaps visible on a shared dashboard or the controls quietly rot.
- Grow into contracts, ABAC and AI-agent controls after the minimum set is real.
Keep reading
- How I Structure Microsoft Fabric Workspaces for Dev, Test and Prod
- Migrating from Hive Metastore to Unity Catalog: A Practitioner’s Runbook
- Data Quality Rules That Actually Get Enforced: A Bronze-to-Gold Playbook
Running a leaner (or heavier) governance model on your lakehouse? I’d be glad to compare notes. Leave a comment or get in touch.
Sources
- Microsoft Learn: Get started with data governance in Fabric
- Microsoft Learn: Governance and compliance in Fabric
- Microsoft Learn: Information protection in Fabric
- Microsoft Learn: Tags in Microsoft Fabric
- Databricks: What is Unity Catalog?
- Databricks: Governed tags
- Databricks: ABAC core concepts
- Microsoft Learn: Unity Catalog data classification
Views on this site are my own and don’t represent my employer. This post is for general information only; see the Disclaimer.
Leave a Reply